What are probabilistic sample types?
4 min read
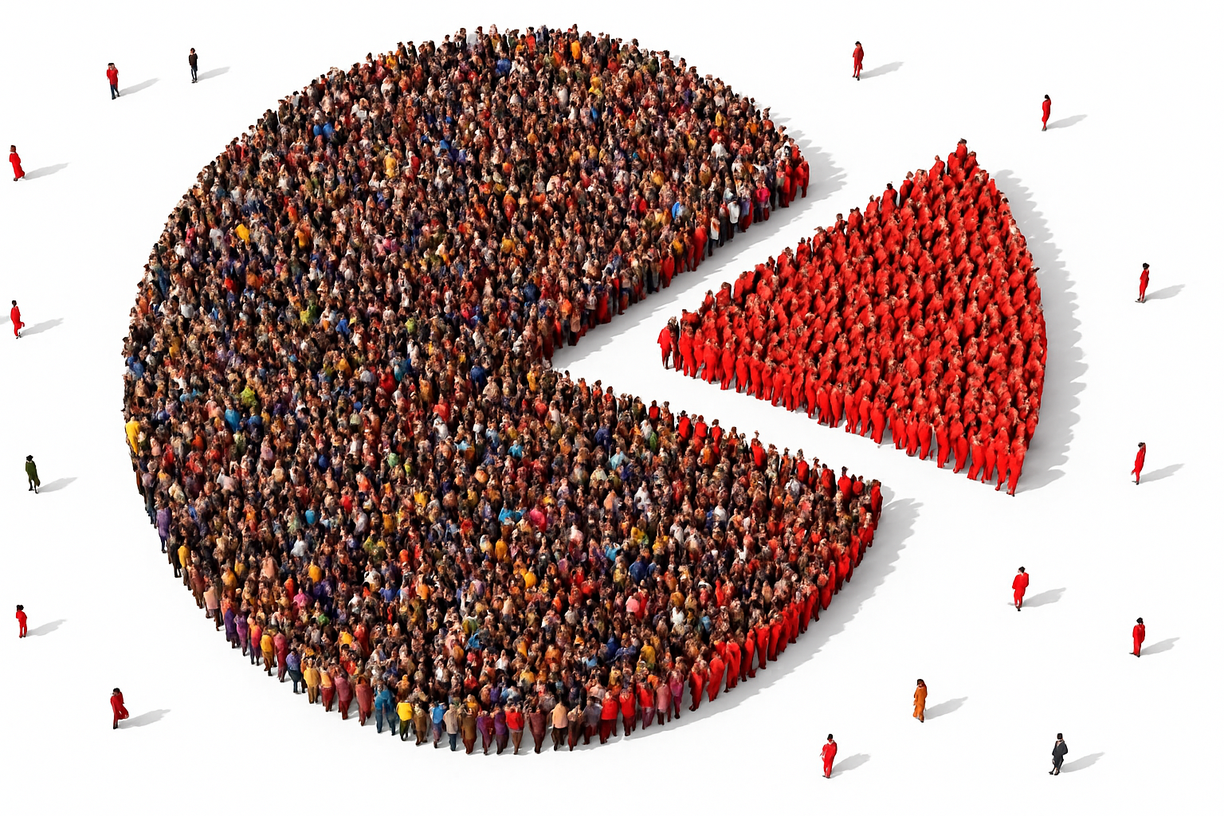
When we talk about market research, we ensure the credibility of information based on how we choose participants. If the selection is not done in a structured way, the results lose consistency and no longer represent reality. This is precisely where probabilistic sample types come in, techniques that ensure representativeness, reduce biases, and increase confidence in the data.
By adopting probabilistic sampling, we significantly increase the statistical precision and scientific validity of the study. In this way, we can not only analyze a specific group but also generalize the results to the entire population with confidence. Therefore, this method becomes indispensable when the objective is to extract reliable insights applicable in different contexts, from business strategies to academic and social surveys.
What is a probabilistic sample?
Objectively, a probabilistic sample is a method in which all individuals in the population have the same known chance of participating in the study. In other words, the selection occurs randomly and transparently.
In contrast, non-probabilistic sampling depends on choices made for convenience, accessibility, or the researcher's judgment, which can compromise accuracy. Probabilistic sampling stands out precisely because it ensures that the data reflects reality with greater statistical rigor.
By adopting this method, companies, researchers, and organizations can make more solid decisions based on representative data.
Read also: Maximizing Precision: Exploring Sample Types for Research
Main types of probabilistic samples
Below, we detail the main types of probabilistic samples, with their applications and advantages:
1. Simple Random Sample
This is the most basic type and, at the same time, one of the most efficient. Here, all individuals have the same probability of being selected. For this, manual draws or digital randomization systems are used.
-
Practical example: in a database with 10 thousand customers, a company can randomly select 200 names to assess the level of satisfaction with its services.
-
Advantage: as everyone has the same chance of inclusion, this model avoids favoritism and ensures impartiality.
In other words, it is an ideal method when seeking simplicity without sacrificing representativeness.
2. Systematic Sample
In this model, selection follows a sequential logic. First, a starting point is chosen randomly; then, a fixed interval is established to select the next elements.
-
Practical example: in a list of 5.000 customers, the starting point can be drawn, and from there, every 50 names are selected.
-
Advantage: this type of sampling is very useful in large databases, as it simplifies the selection process and still ensures representativeness.
Furthermore, systematic sampling is especially effective when data is organized homogeneously, avoiding distortions.
3. Stratified Sample
When the population has different characteristics, stratified sampling becomes the ideal choice. In this model, the population is divided into homogeneous strata — such as age group, gender, or region — and selection is carried out proportionally within each group.
-
Practical example: in a national electoral survey, it is necessary to ensure that men and women of different ages and regions are represented according to their proportion in the population.
-
Advantage: this method ensures that relevant groups are not under or over-represented, bringing balance to the analysis.
Thus, stratified sampling is indispensable when the diversity of the population can directly influence the results.
4. Cluster Sample
Unlike the others, cluster sampling does not select individuals directly, but rather entire groups. These clusters can be schools, neighborhoods, cities, or any natural grouping of the population.
-
Practical example: in a survey on reading habits, instead of selecting individuals across the country, specific schools are chosen, and all students from these institutions participate.
-
Advantage: this method reduces costs and time, as it concentrates data collection in delimited areas or groups, without losing representativeness.
However, it is important to note that the quality of the result depends on the diversity of the chosen clusters.
Another Article worth reading: Respondent Sample in Latin America: The Essential Guide
Why choose probabilistic sampling?
Given the different methods, the question arises: why opt for probabilistic sampling? The answer lies in the benefits it provides:
-
Representativeness: the sample faithfully reflects the population.
-
Reliability: the collected data is more robust and less subject to biases.
-
Statistical validity: results can be generalized with confidence.
-
Accuracy: sampling errors can be measured and controlled with greater clarity.
Therefore, by using probabilistic sample types, researchers and companies can base their strategies on consistent information, strengthening decision-making.
Learn more: What defines a good sample: size, profile, or engagement?
The importance of probabilistic sample types for research
Understanding probabilistic sample types strengthens any study seeking reliable data. By applying this method, researchers and companies reduce biases, increase statistical precision, and faithfully reflect the reality of the studied population.
Furthermore, this technique ensures transparency, scientific validity, and consistency, indispensable elements for robust analyses. Therefore, when we use probabilistic sampling in academic research, public opinion surveys, or market studies, we achieve results that truly support strategic decisions.
At PainelTAP, we apply probabilistic sample types with methodological rigor and advanced technology. In this way, we deliver solid, relevant, and actionable insights. Our commitment is to transform data into strategic information that guides companies to make more assertive decisions and achieve competitive advantage.
Why sample size changes everything in the results
What are non-probabilistic sample types?